NakodaX
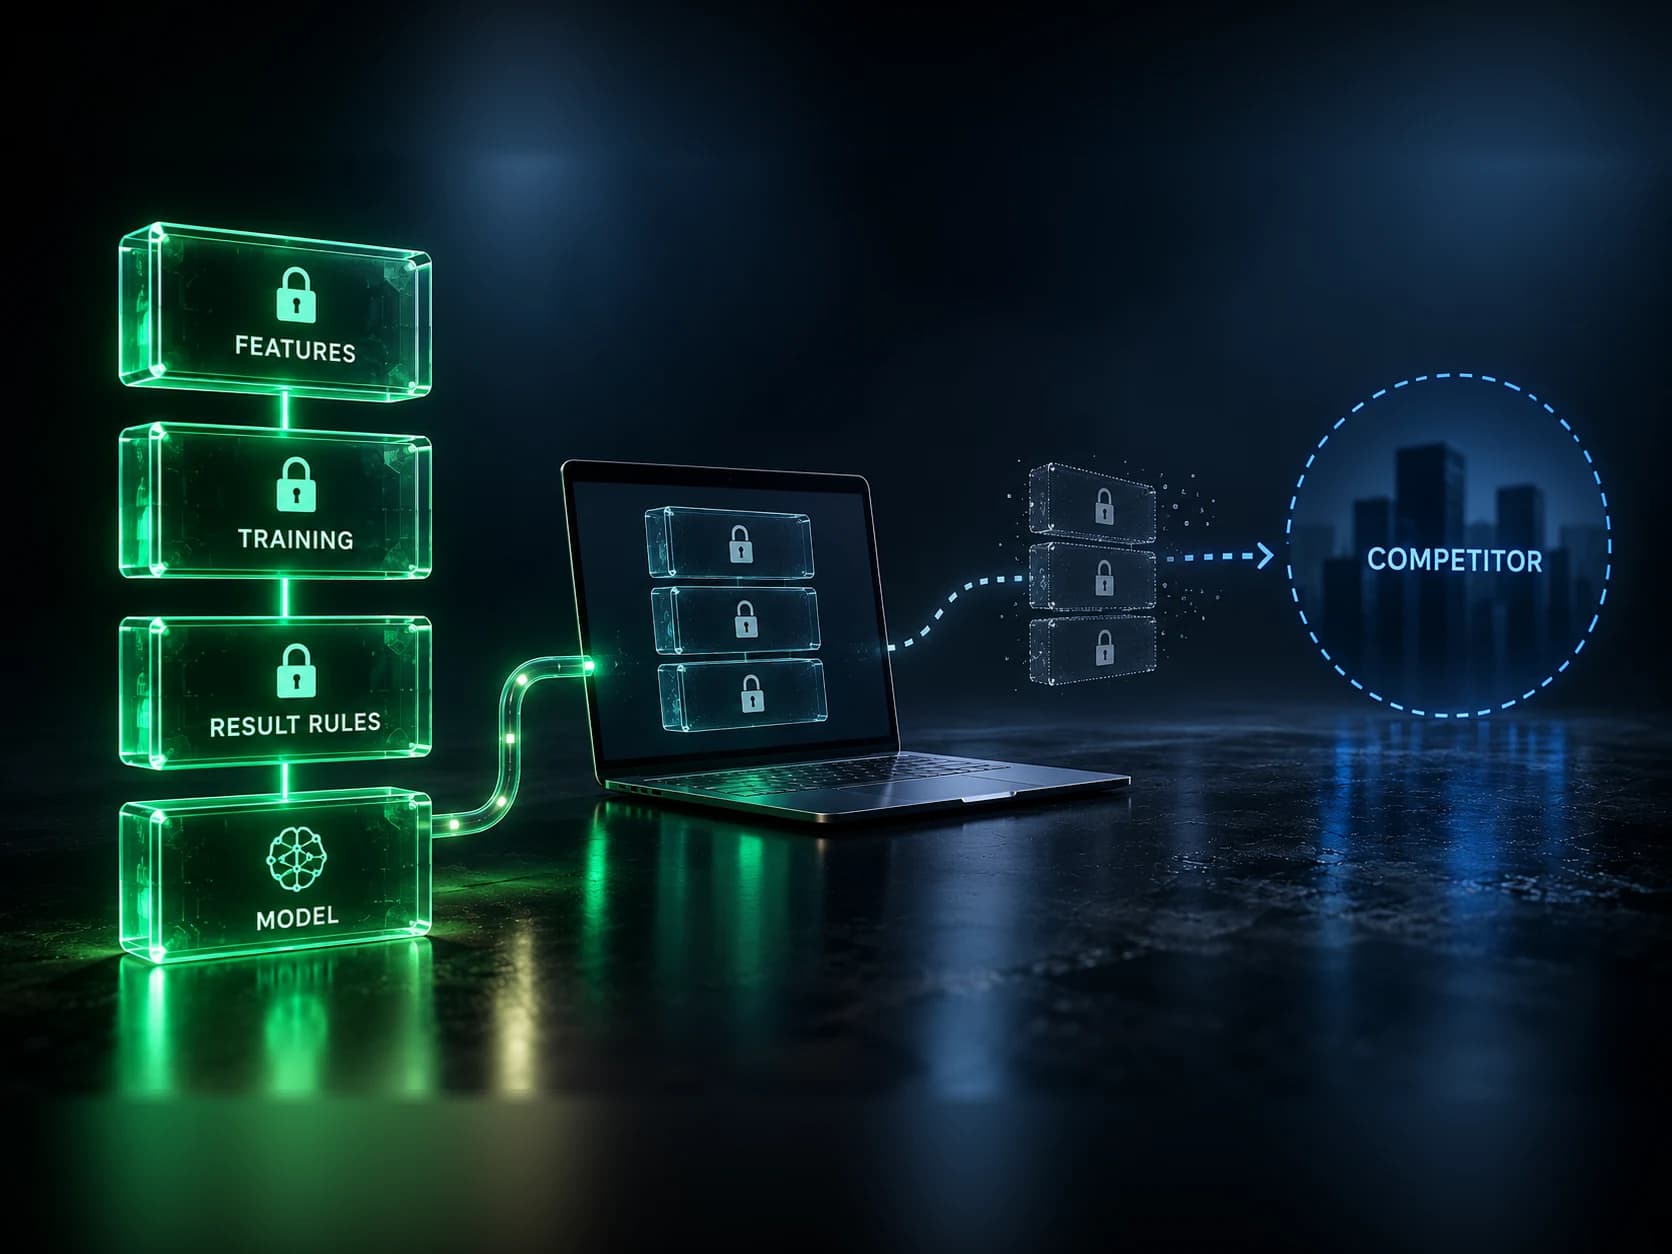
A machine learning pipeline of locked code modules staying behind as a data scientist departs.

Situations· Source Protection

How do you protect your machine learning code when a data scientist leaves?

Lock the Python files that hold your feature logic and training steps, so a departing team member does not leave with a working copy.

What changes

The Python files that hold your business logic are locked. The team builds against stand ins, a few named people open the real code with approval, and production runs the locked files under a licence.

In short

The value of a machine learning product is often in the code around the model: feature logic, training steps and result rules. That is plain Python every data scientist holds. Lock those files, so the team builds against stand ins and a departing member takes no working copy.

What happens today

Your company has a model that predicts loan defaults, or fraud, or demand. It works better than the competition’s, and your customers pay for that.

The model is not the hard part. The hard part took two years: which signals to use, how to clean and combine them, how to train, and the rules that adjust the model’s output before a customer sees it. All of that lives in Python files in your repository.

Every data scientist and ML engineer on the team has the full repository on their laptop, in notebooks on their own machines, and often in a personal GitHub account. One of them accepts an offer from a competitor.

How the leak happens

Anyone who works on the model can read every step: the features, the training and the adjustments. When one of them joins a competitor or starts a company in the same space, they take that recipe with them.

With your feature logic and training steps in hand, a new team can train a similar model on their own data in weeks, not years. An AI tool can rewrite the pipeline with new names and structure, so it no longer looks like your code.

What it costs you

Your accuracy advantage, the reason customers pay you, shows up in a competitor’s product. Two years of experiments are skipped by someone else. Proving the copy is close to impossible once the code has been rewritten.

What most companies do today, and where it falls short

An NDA and an IP clause give you a legal claim but do not remove a copy. An exit checklist and laptop return cover the company laptop, not home machines, personal accounts or notebooks shared earlier.

Removing repository access stops new copies after the last day, not the ones made before it. Keeping the model behind an API protects the model itself, not the pipeline code the team works on every day.

How NakodaX changes this

Most of an ML codebase is boilerplate: loading data, logging, config, serving the model, dashboards. Your business logic, the feature building, training steps and result rules, sits separately in its own files. NakodaX scans your repository and suggests those files. You review the list and decide what to protect.

Those Python files are encrypted. The wider team works on a protected copy, where the locked files are replaced by stand ins. A stand in takes the same inputs as the real code and gives back a result, so people can build and test around it. The real logic is not inside it.

The few people who work on the business logic open it through a change session: someone asks, a second admin approves, the window has an end date, and everything is logged. Your production systems run the locked files under a licence, and the code opens only in the memory of the running process.

When someone leaves, the business logic files on their machine are encrypted. They cannot be read or run without a key from NakodaX.

What changes for your team, and what does not

NakodaX does not change your original repository. It builds a new, protected repository next to it, where the files that hold your business logic are locked and replaced by stand ins. The protected repository keeps no history of those files, so earlier versions of the protected code are not in it and cannot be recovered from it.

To get the benefit, your team runs a switch over: the whole team stops working in the original repository and moves to the protected one. Once they are cut off from the original, all new work happens against stand ins.

Copies made before the switch are not changed. A team member who already holds a readable copy of the pipeline still has it. NakodaX protects from the day you switch: new work, new hires, and every departure after it.

This page is about code. The trained model file is not covered here, and training data and datasets are covered by NakodaX Data Protection. It cannot stop someone remembering the approach they learned.

People who open the real files in a change session can read them during that window. Today it works with Python, JavaScript, TypeScript and SQL.

What changes

The Python files that hold your business logic are locked. The team builds against stand ins, a few named people open the real code with approval, and production runs the locked files under a licence.

Answers

Related questions

How do I protect ML code when a data scientist leaves?
Lock the Python files that hold your feature logic, training steps and result rules. Most of the team works with stand ins, a few named people open the real files with approval, and a copy taken on the way out cannot be read or run.
Is the model or the code the valuable part?
Often the code. The way features are built and results are adjusted is what makes a model work well, and that lives in ordinary Python files that are easy to copy.
Can a former employee rebuild our model with AI?
With a readable copy of your pipeline, it becomes much faster. Locked files are encrypted, so there is nothing readable to give an AI tool.

This one, or one very like it

IP protection. Start where the problem actually is.